Wall Street is quietly scrambling to offload a massive pile of AI data center debt, highlighted by JPMorgan and MUFG spending over six months trying to shift $38 billion in construction loans tied to Oracle projects in Texas and Wisconsin. When major lenders hit their exposure limits and credit default swaps climb to levels not seen since 2009, the message for manufacturers is clear. The era of writing blank checks for speculative AI infrastructure is ending.
For operations and quality leaders, this financial pullback changes how you should evaluate your own technology investments. Instead of chasing costly infrastructure experiments, you need a pragmatic strategy focused on proven software that eliminates manual bottlenecks and delivers immediate operational ROI. Here is how to stop burning capital on hype and start applying AI where it actually protects your margins.
Wall Street Hits the Pause Button on AI Infrastructure Debt
The mechanism banks are reaching for tells you plenty. Significant risk transfers let a lender keep a loan on its books while selling the riskiest slice to outside investors. Morgan Stanley and SMBC have been exploring them alongside the others, not because the deals went bad, but because every one of them has run into internal caps on how much AI-linked exposure a single bank can hold.
Matthew Moniot, co-head of credit risk sharing at Man Group, put the scale plainly to the Financial Times:
the deal sizes involved are “out of scale to anything we’ve thought about, ever.”
That is a professional risk pricer admitting the numbers break his models. Some lenders are now selling pieces to non-bank buyers at a discount just to clear them. Discounted exits are not confidence.
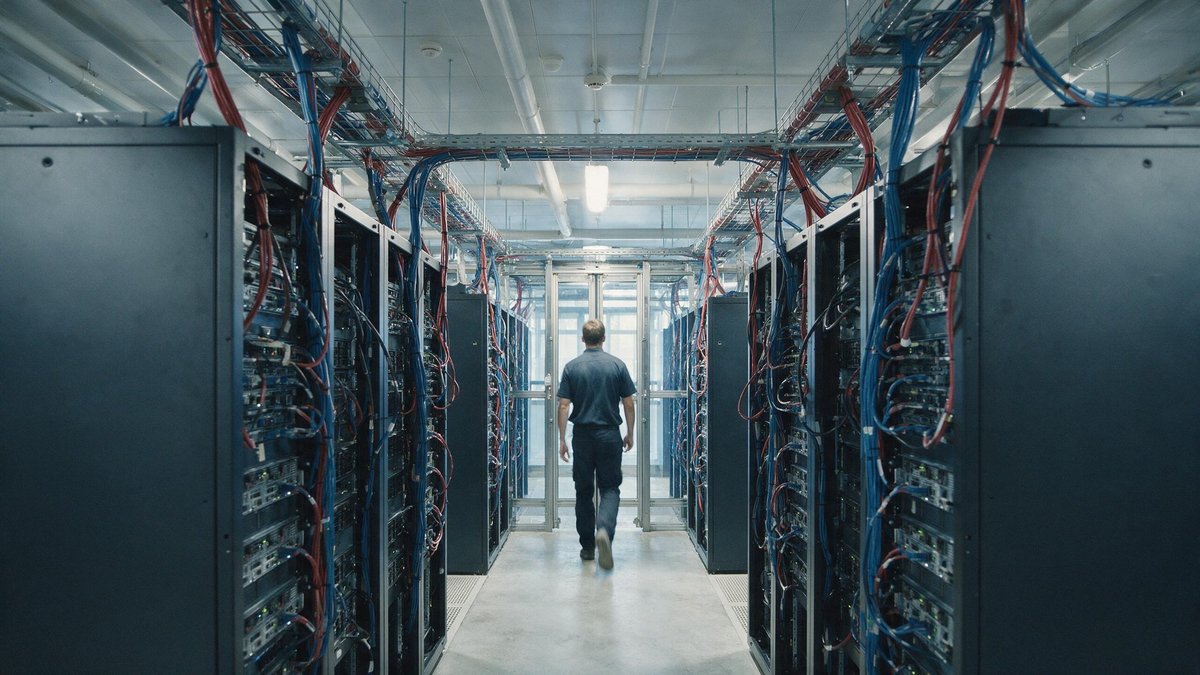
Inside the $38 Billion Oracle Data Center Exposure
The risk transfer mechanics keeping banks exposed
When lenders hit internal concentration limits on heavy infrastructure bets, they do not simply write off the balance sheet. They engineer financial workarounds like significant risk transfers to offload the most volatile tranches to outside parties while keeping the primary loans officially registered.
This reality underpins the exact friction currently gripping institutions that backed massive computational real estate. A consortium including JPMorgan and MUFG has spent more than six months trying to distribute construction debt tied to Oracle projects.
Matthew Moniot of Man Group described the scale plainly to the Financial Times, noting that the deal sizes involved are out of scale to anything his firm has evaluated ever before. When pricing experts call the numbers unprecedented, enterprise leaders must recognize that financial markets are drawing a hard boundary around speculative capacity.
Record credit default swaps and collateral disputes
The broader market is pricing this strain into corporate health metrics with absolute clarity. S&P downgraded Oracle to BBB- back in July, pushing the credit rating a single notch above junk status.
That downgrade followed escalating friction over capital requirements, including an Oracle lawsuit against the Wisconsin Public Service Commission. The regulatory dispute stems from a rule that could force the tech giant to post more than $7 billion in collateral for its Port Washington facility.
Market confidence reflects these capital demands directly. Five-year credit default swaps for insuring against Oracle defaulting climbed to around 151 basis points in early October, reaching levels not seen since 2009. Manufacturing executives who buy software or infrastructure must look at these indicators as proof that debt-fueled vendor expansion carries structural risk.
Why Speculative Infrastructure Overhang Matters to Operations Leaders
Shifting from limitless compute assumptions to cost discipline
For years, enterprise software vendors and cloud providers operated under a simple premise. Compute was functionally infinite, and the capital to build more of it would always flow freely from institutional lenders. When banks struggle for over six months to distribute billions in construction debt for data centers, that era of cheap, boundless capacity closes. Infrastructure financing corrections hit the wider market through rising cloud fees, tighter API limits, and higher subscription prices for enterprise tooling.
Operations leaders can no longer build automation roadmaps that assume brute force processing power will mask inefficient workflows. When running heavy computer vision or predictive maintenance models starts driving up operational expenses, optimization stops being optional. You have to scrutinize every pipeline to ensure you are only processing high-value data. Efficiency in your tech stack directly dictates whether your automation initiatives generate margin or drain it.
Matthew Moniot, co-head of credit risk sharing at Man Group, described the massive debt piles involved in these builds as being “out of scale to anything we’ve thought about, ever.” That kind of foundational exposure forces a recalibration across the entire supply chain of technology. Vendors who rely on subsidized capital and endless venture rounds must suddenly prove they can turn a profit without endless cash injections. If your operations depend on their software, their financial exposure becomes your operational risk.
Evaluating vendor staying power in your tech stack
The tightening credit environment means your software and hardware vendors face harsher borrowing terms. Companies carrying heavy debt loads to fund regional facilities or massive compute clusters will pass those costs down to customers or slash research and development budgets. That leaves quality managers and operations directors vulnerable to sudden product sunsets, sluggish support, or abrupt price hikes. Vet your technology partners for financial stability just as strictly as you vet your raw material suppliers.
Look closely at how your software providers fund their operations. Relying on startups that survive purely on continuous rounds of venture funding is a liability when capital markets freeze. Prioritize vendors who demonstrate clear operational efficiency and positive cash flow over those chasing market share through aggressive, debt-financed expansion. Your manufacturing lines and quality assurance systems need stable partners that will still be around to support your infrastructure three years from now.
Building a resilient tech stack requires cutting out bloated enterprise software that charges exorbitant fees for basic automation features. Focus on lean, purpose-built implementations that solve specific bottlenecks on the shop floor without requiring massive server farms. When the financial foundation of the tech sector shakes, pragmatism and low overhead protect your operational continuity better than any unproven platform.
Ready to find AI opportunities in your business?
Book a Free AI Opportunity Audit. It is a 30-minute call where we map the highest-value automations in your operation.
Practical AI Implementation Without Infrastructure Gamble
Prioritizing internal workflows that eliminate manual work
Operations leaders must stop waiting for massive cloud architectures or endless compute capacity to solve daily floor problems. The current credit crunch proves that relying on hyperscale expansion is a losing bet. Instead, focus internal resources on localized processes that consume minimal computing power while removing heavy administrative friction.
Targeted automation handles repetitive scheduling, inventory reconciliation, and document routing without requiring dedicated data center space. Eliminating manual touchpoints in these areas speeds up throughput immediately. Quality managers see better error catch rates when software handles routine data entry tasks instead of exhausted personnel.
Measuring capital efficiency over raw parameter counts
Budget allocation needs to shift away from chasing massive model sizes and toward proven, high-speed task completion. Large parameters demand heavy infrastructure backing that Wall Street is quietly retreating from. Evaluating tools based on cost per completed task keeps capital expenditures strictly aligned with actual operational output.
Manufacturers achieve faster payback periods by deploying focused machine learning models that run efficiently on existing factory hardware. Tracking actual hours saved per shift provides a clear metric for financial viability. Prudent deployment models ensure factory floors remain productive without exposing the business to the financing turbulence currently hitting heavy infrastructure.
Factory floors already possess plenty of processing muscle hidden inside modern PLCs, inspection cameras, and local servers. Directing localized analytics toward machine wear patterns prevents unexpected downtime without sending gigabytes of telemetry to remote warehouses. Maintaining local data pipelines keeps operations independent of external cloud pricing shifts.
Procurement teams need to scrutinize software vendors who push resource-heavy architectures. Asking technical partners to prove their algorithms run on standard edge devices filters out inefficient programming. Vendors should demonstrate how their systems minimize memory footprints while maintaining high accuracy on repetitive inspection duties.
Quality assurance benefits directly from smaller, specialized models trained on specific defect datasets rather than generalized neural networks trying to learn every manufacturing variable. A targeted vision system inspecting soldered joints requires a fraction of the electricity and computing power demanded by general enterprise platforms. Precision in scope matches precision in execution.
Facility directors should audit current software licenses to identify idle compute resources sitting right inside existing plant automation equipment. Repurposing these assets for targeted machine learning tasks avoids new capital requests entirely. Treating internal processing hardware as a fixed budget forces better engineering choices and eliminates wasteful data hoarding.
Source: startupfortune.com